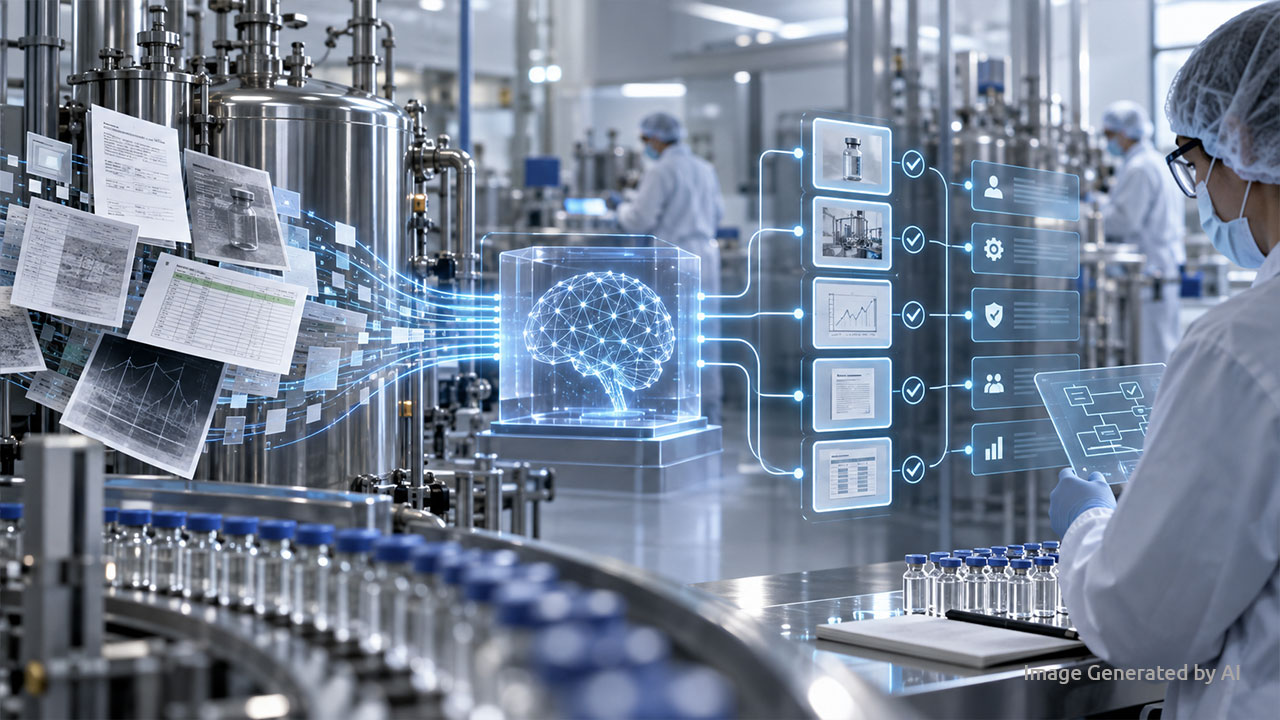
A pharmaceutical regulatory response team spends 30 days on a single agency question. Most of that time goes to finding documents. At the Industrial AI Summit 2026, Kristen Sauter, President and General Manager of Life Sciences, Adlib Software, and Adam Procopio, Scientific Associate Vice President, Merck, explained why: every time a contract manufacturer’s electronic batch record crosses into the pharmaceutical company’s system, it arrives as a PDF stripped of the structure that AI needs to trace decisions back to source data.
Why Do Documents Break AI Traceability in Pharma?
Every time two systems exchange data, a new generation of documents gets produced. A contract development and manufacturing organization may run a full electronic batch record internally, capturing sensor-level values in a structured digital format. When that record arrives at the pharmaceutical company, it has been converted to a PDF. The structure that existed at the origin is gone. Engineers look at the model, auditors look at the record, but traceability fails at the documents that sit between the two. The number of system interactions is increasing, and each interaction regenerates documents in ways that lose structure. Adam calls this problem “unknown knowns”: the data exists somewhere in the enterprise but is very difficult to find. Maya Schushan-Orgad, Sr. Director, Open Innovation Platform Lead, Teva Pharmaceuticals, added that the heterogeneity of machines and formats across manufacturing sites compounds the problem, making it harder to trace data back to its origin.
Who Owns Traceability When a Partner Manufactures the Product?
Pharmaceutical companies outsource manufacturing to CDMOs but retain full regulatory accountability for the dossier. “We can outsource the work. We can’t outsource accountability,” said Adam Procopio, Scientific Associate Vice President at Merck. Regulators expect the pharmaceutical company to own the integrity of every document behind a filing, including data generated in a partner’s facility. The pharmaceutical company must ingest fragmented spreadsheets, scanned batch records, and non-readable PDFs from external partners and convert them into a data schema that its own AI systems can reference and cite. Two years ago, structuring decades of legacy unstructured data would have been described as an insurmountable task. Adam noted that agentic AI approaches have changed that calculation: tasking an agent to structure unstructured data is now feasible for organizations willing to spend on the tokens.
Should Companies Fix Their Document Archive or Start Fresh?
Adlib’s answer: start today, work forward, and do not begin with the archive. Reconstructing traceability after the fact is not defensible. Building it at the source is the only approach that survives regulatory scrutiny. Agencies and health authorities are moving toward data-driven submissions, which means positioning current data practices for that future rather than spending resources on a backlog that predates modern data requirements. When asked about reconstruction, the response was four words: “Don’t do it.” The FDA’s recent guidance on AI in regulatory decision-making represents, in Adlib’s assessment, a signal that the agency is open to discuss AI utilization, not a blueprint for implementation. Companies calibrating how aggressively to adopt AI-driven compliance workflows should read the guidance accordingly.
This article is based on a panel discussion at the Industrial AI Summit 2026 featuring Adam Procopio of Merck, Kristen Sauter of Adlib Software, and Maya Schushan-Orgad of Teva Pharmaceuticals, moderated by Rick Franzosa of Tech-Clarity. AI tools were used to help summarize and organize the content. Reviewed and edited by the IIoT World editorial team.
Editorially Independent, Sponsored by Adlib Software